Context.dev
 image
Scrape without managing proxies
Still rotating proxies to get a page to load? Let Context.dev handle it. Scrape with built-in rendering and stealth, then get the data in the format you need.

Loading YC ads…
YC S26 · Meta Ads
We give AI agents realtime web context via API
28 saved ads · one primary angle per ad.
View all creatives8 of 28 ads contain video.
Button captured for 28 of 28 ads.
Days old when observed · n=28.
Median 20.3s · 8 unique videos.
Labels can overlap · n=28 saved ads.
No exact copy repetition in the saved selection.
Based on 28 saved ads, observed 2026-10-19. This is a curated selection capped at 50 ads, not a random sample. Percentages describe saved ads, not impressions or budget.
Angles are assigned automatically using rules written specifically for Context.dev. Rules run in order: first match in the headline, then in the body. This classifies saved copy; it does not include scene analysis or video transcription.
Formats are based on saved files. Multiple images alone do not confirm a carousel. Ad age uses 28 known start dates; 0 are unknown. Days are measured from Meta’s start date to each ad’s recorded observation date. Age does not establish continuous delivery or profitability.
Video duration was measured from MP4 metadata for 8 of 8 unique video files. Exact duplicates count once. CTA labels are captured button text, not verified user actions; unknown labels are included in the distribution.
Offer signals detect words in saved body copy and headlines. Labels overlap and are not verified advertising claims. Unsaved variants may use different formats and CTAs.
Distinct media sets use exact file SHA-256 hashes: 28 sets, with 0 repetitions beyond the first occurrence. Visually similar variants may have different hashes. Text comparison ignores URLs, letter case and extra whitespace. Different headlines count as different text. Repeated copy does not prove a controlled A/B test.
Impressions, spend, CTR, conversions and ROAS are unavailable. A single snapshot cannot establish stopped ads, growth or turnover. Ad count is not campaign count.
storefront|pricing|product page|product detailssignup|enriched|work email\bsearch|ground|cite|Claudeprox|hardest|hard pages|difficult|different scraper|broken|fixing|captcha|block|scraping infra|scraper.*fail|troubleshootMarkdown|every format|JSON|structuredagent|AI|web|scrap|URLCreative archive
Last updated
imageStill rotating proxies to get a page to load? Let Context.dev handle it. Scrape with built-in rendering and stealth, then get the data in the format you need.
 image
Got a URL your scraper keeps failing on? Put Context.dev to the test. Bring your hardest pages and start with 1,000 free credits.
Turn any product page into clean, structured data. Context.dev extracts product details from e-commerce sites so your agents and apps can actually use them.
 image
The pages you need aren’t always easy to scrape. Bring them to Context.dev. Browser rendering, stealth, and automatic proxy escalation are built in.
Build AI services people will actually pay for. Context.dev gives your apps and agents live web data — search, scrape, monitor, crawl, and extract through one API.
 image
“Sorry, I can’t access that website.” Fix that. Give your agent a scraping API that reads live pages and returns clean Markdown. Try it with 1,000 free credits.
 image
Let your agent search the live web in plain language. Context.dev turns one question into parallel searches and returns ranked results with the key passages. Try it with 1,000 free credits.
 image
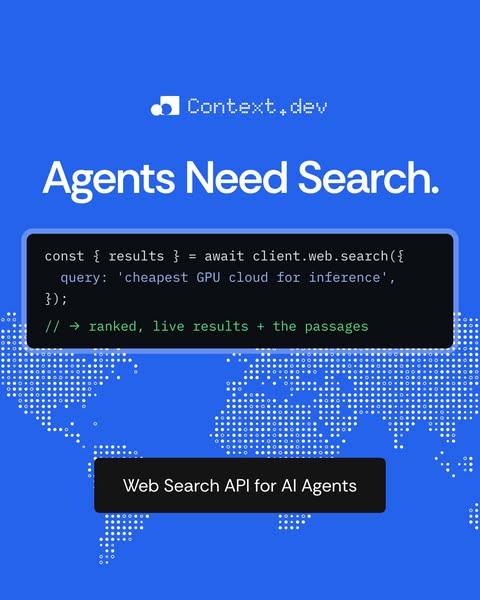
Add web search to your agent with one SDK call. Ask in plain language and get ranked, live results with highlighted passages. Start with 1,000 free credits.
 image
Training data goes stale. Give your agent live web search with ranked results and the passages that matter, so it answers from today’s web. Start with 1,000 free credits.
 image
Search built for agents, not people scrolling. Each result comes back with its title, URL, relevance, and passages, ready for your model. Get 1,000 free credits.
 image
Selectors change. Sites push back. Your scraper breaks again. Replace it with one API call that renders the page and returns clean JSON or Markdown. Get 1,000 free credits.
 image
Bot walls, heavy JavaScript, proxy rotation. Context.dev deals with all of it so your requests come back with data. Test your toughest URLs with 1,000 free credits.
 image
Give your agent real sources. Context.dev search returns live results with URLs and passages, so every answer can point to where it came from. Start with 1,000 free credits.
 image
Most search APIs hand your agent a list of links. Context.dev returns ranked, live results with the page content included, ready to ground answers. Start with 1,000 free credits.
Your app needs data from the web. Your agent needs that data structured and usable. Context handles everything in between.
Your app needs the web. It doesn’t need another scraping stack. Context.dev handles the rendering, proxies, retries, crawling, and extraction behind one API.
Stop guessing what to charge. Pull live pricing and competitor data from the web with Context.dev.
Search, scrape, and extract live web data.
Your AI can’t know what’s happening on the web if it can’t see the web. Give your agents live search, scraping, research, and fresh website data with Context.dev.
 image
JavaScript-heavy pages? Scrapers getting blocked? Context.dev handles browser rendering and automatic proxy escalation so you can focus on using the data.
 image
Before you spend another afternoon fixing your scraper, try the same URL with Context.dev. Get 1,000 free credits and compare the results yourself.
 image
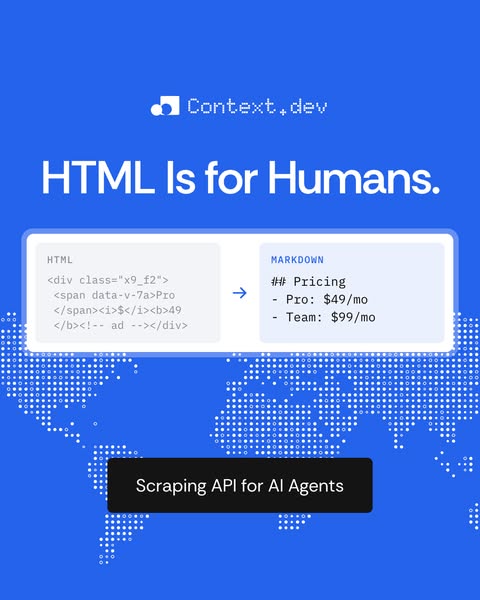
Your agent doesn't need div soup. Context.dev turns a URL into clean, LLM-ready Markdown your agent can use right away. Start with 1,000 free credits.
Stop making users fill out everything you can already find on the web. Context.dev turns a work email into structured company data automatically.
 image
Markdown, HTML, screenshots, images, and structured JSON. Get the formats your app needs in one scrape call. Try it with 1,000 free credits.